Publications / Top Conferences
Intelligent Predictive Maintenance RAG Framework for Power Plants: Enhancing QA with StyleDFS and Domain Specific Instruction Tuning
EMNLP 2024 · Industry Track · Oct 2024
Abstract
Process plants are complex large-scale industrial facilities that convert raw materials or intermediate products into final products, requiring continuous processes with high safety and efficiency standards. In particular, in nuclear process plants, Predictive Maintenance System (PMS) plays a critical role in predicting equipment anomalies and performing preventive maintenance. However, current PMS relies heavily on the experience of a few experts, leading to knowledge loss upon their retirement and difficulty in swift response. Existing off-premise Question-Answering (QA) systems based on Large Language Models (LLM) face issues such as data leakage and challenges in domain-specific tuning. To address these problems, this study proposes an on-premise intelligent PMS framework utilizing a new chunking method, StyleDFS, which effectively reflects the structural information of documents. Additionally, we demonstrate that Instruction tuning using relevant domain-specific data improves LLM performance even under limited data conditions.
Key Contribution
Domain-specific RAG framework for scientific and industrial QA; led to two technology transfers.
Method
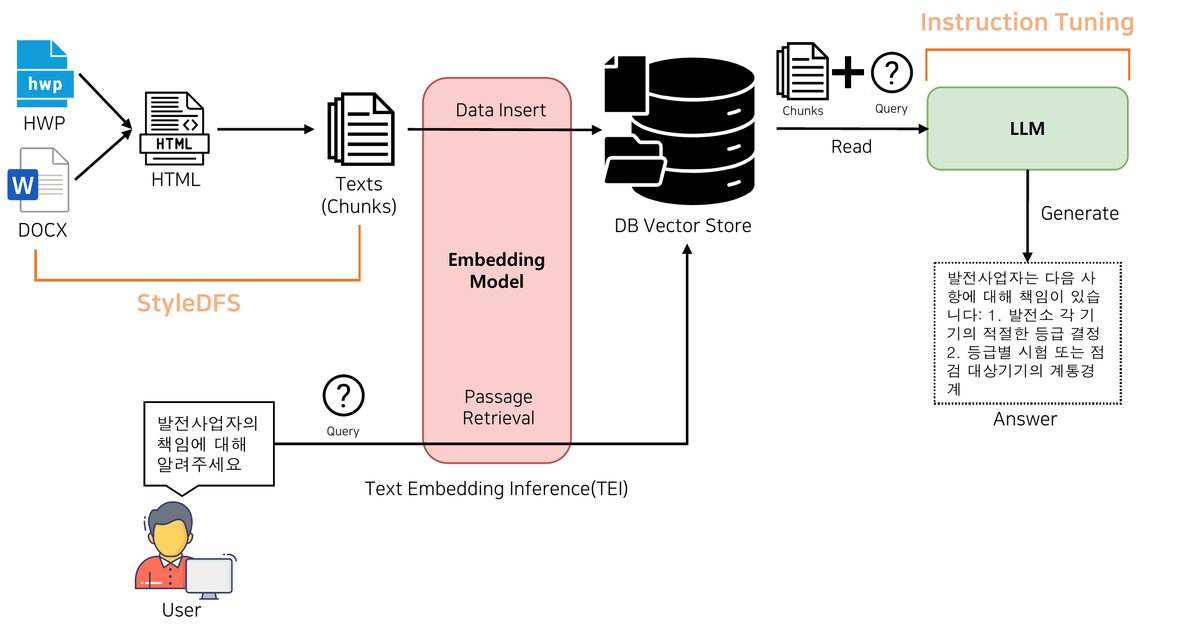
The framework targets predictive maintenance in nuclear process plants, where maintenance knowledge lives in long structured documents (mainly HWP and DOCX) and must stay on-premise.
- StyleDFS chunking. Documents are converted to HTML while preserving their structure. The style classes that the converter assigns to each HTML element define a tree in which titles, body text, subsections, and lists become separate nodes. A preorder depth-first search then accumulates text from leaf nodes and their parents; when the accumulated text exceeds the maximum length, the chunk is closed and a new one starts from the right sibling, keeping the parent node's text so that each chunk retains its section context.
- Retrieval. Among Korean-capable embedding models from the MTEB leaderboard, multilingual-e5-large gives the best nDCG@3 on Ko-StrategyQA, Ko-mrtydi, and Ko-miracl and is used for retrieval. Chunk embeddings are stored in PostgreSQL and served with Text Embedding Inference (TEI) so that a single GPU can handle multiple users.
- Domain-specific instruction tuning. MRC data from science and technology documents is rewritten into descriptive answers with GPT-4 and used to instruction-tune Llama-3-8B, Llama-3-Open-Ko-8B, gemma-7b, and gemma-ko-7b.
Results
Embedding model selection (nDCG@3).
| Model | Ko-StrategyQA | Ko-mrtydi | Ko-miracl | Average |
|---|---|---|---|---|
| multilingual-e5-large | 0.764 | 0.527 | 0.623 | 0.638 |
| multilingual-e5-base | 0.718 | 0.498 | 0.585 | 0.600 |
| multilingual-e5-small | 0.698 | 0.496 | 0.574 | 0.589 |
| ko-sroberta-multitask | 0.583 | 0.226 | 0.297 | 0.369 |
| UAE-Large-V1 | 0.061 | 0.050 | 0.057 | 0.056 |
| bge-large-en-v1.5 | 0.054 | 0.038 | 0.047 | 0.046 |
Retrieval recall by chunking method across n-gram lengths, at top-1 and top-3.
| Chunking | Top-k | 1-gram | 2-gram | 3-gram |
|---|---|---|---|---|
| Length | 1 | 0.2023 | 0.1358 | 0.1066 |
| Length | 3 | 0.3668 | 0.2404 | 0.1862 |
| Semantic | 1 | 0.2464 | 0.1642 | 0.1281 |
| Semantic | 3 | 0.4363 | 0.2935 | 0.2294 |
| StyleDFS | 1 | 0.3595 | 0.2975 | 0.2727 |
| StyleDFS | 3 | 0.5710 | 0.4716 | 0.4326 |
Answer generation (BLEU and ROUGE-L) for base and instruction-tuned models. Gold uses chunks that contain the correct answer.
| Chunking | Top-k | Metric | Llama-3-8B | Llama-3-Open-Ko-8B | gemma-7b | gemma-ko-7b | Average | ||||
|---|---|---|---|---|---|---|---|---|---|---|---|
| base | tune | base | tune | base | tune | base | tune | ||||
| Length | 1 | BLEU | 4.080 | 10.999 | 2.242 | 15.203 | 5.905 | 10.689 | 1.792 | 13.796 | 8.088 |
| Length | 1 | ROUGE-L | 8.433 | 6.700 | 3.332 | 12.065 | 6.118 | 7.886 | 2.177 | 10.370 | 7.259 |
| Length | 3 | BLEU | 5.665 | 16.235 | 3.598 | 18.973 | 4.942 | 10.330 | 3.263 | 20.449 | 10.556 |
| Length | 3 | ROUGE-L | 9.345 | 12.417 | 7.015 | 17.966 | 7.669 | 6.393 | 5.041 | 14.124 | 9.746 |
| Semantic | 1 | BLEU | 6.219 | 11.704 | 3.038 | 16.993 | 4.005 | 10.077 | 1.409 | 15.239 | 8.085 |
| Semantic | 1 | ROUGE-L | 7.551 | 7.305 | 4.356 | 13.710 | 7.841 | 7.672 | 2.074 | 8.821 | 7.041 |
| Semantic | 3 | BLEU | 5.913 | 17.703 | 4.425 | 20.646 | 4.075 | 10.954 | 3.000 | 19.976 | 10.961 |
| Semantic | 3 | ROUGE-L | 8.049 | 9.423 | 5.940 | 13.806 | 7.587 | 9.694 | 4.026 | 13.245 | 8.971 |
| StyleDFS | 1 | BLEU | 3.356 | 13.671 | 3.120 | 19.072 | 5.924 | 16.514 | 5.397 | 17.510 | 10.070 |
| StyleDFS | 1 | ROUGE-L | 6.235 | 13.746 | 6.012 | 13.046 | 11.005 | 14.773 | 7.102 | 13.818 | 10.216 |
| StyleDFS | 3 | BLEU | 3.479 | 19.579 | 2.705 | 23.138 | 6.626 | 17.595 | 8.401 | 20.486 | 12.500 |
| StyleDFS | 3 | ROUGE-L | 5.098 | 18.245 | 5.405 | 16.949 | 8.547 | 13.084 | 9.242 | 16.447 | 11.377 |
| Gold | - | BLEU | 10.049 | 24.103 | 4.267 | 31.612 | 11.798 | 21.479 | 8.030 | 29.486 | 17.478 |
| Gold | - | ROUGE-L | 9.939 | 21.200 | 7.947 | 22.930 | 16.409 | 13.676 | 10.027 | 15.436 | 14.945 |
- StyleDFS gives the highest retrieval recall in every setting, for example 0.3595 (top-1) and 0.5710 (top-3) for 1-gram, compared with 0.2464 and 0.4363 for semantic chunking.
- Averaged over the four models, StyleDFS gives the highest BLEU and ROUGE-L among the three chunking methods in both the top-1 and top-3 settings; answers generated from gold chunks remain higher.
- The instruction-tuned model scores higher than its base model in 51 of the 56 base/tune pairs in the generation table.
BibTeX
@inproceedings{hong-etal-2024-intelligent,
    title = "Intelligent Predictive Maintenance {RAG} framework for Power Plants: Enhancing {QA} with {S}tyle{DFS} and Domain Specific Instruction Tuning",
    author = "Hong, Seongtae  and
      Shin, Joong Min  and
      Seo, Jaehyung  and
      Lee, Taemin  and
      Park, Jeongbae  and
      Young, Cho Man  and
      Choi, Byeongho  and
      Lim, Heuiseok",
    editor = "Dernoncourt, Franck  and
      Preo{\c{t}}iuc-Pietro, Daniel  and
      Shimorina, Anastasia",
    booktitle = "Proceedings of the 2024 Conference on Empirical Methods in Natural Language Processing: Industry Track",
    month = nov,
    year = "2024",
    address = "Miami, Florida, US",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2024.emnlp-industry.61/",
    doi = "10.18653/v1/2024.emnlp-industry.61",
    pages = "805--820"
}